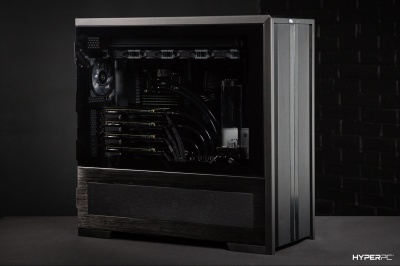
HYPERPC AMPERE 9 ULTRA
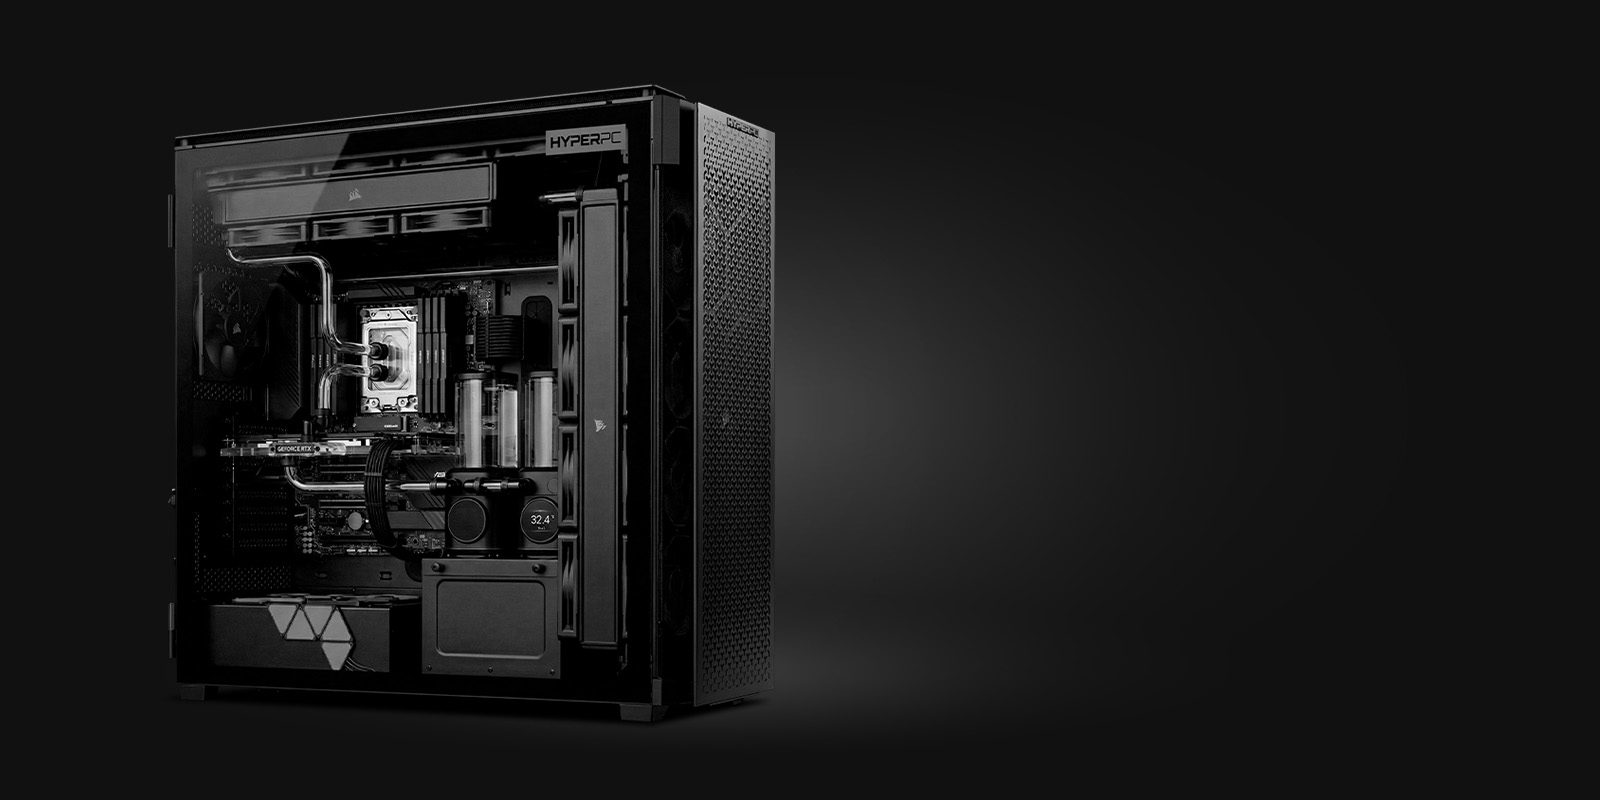
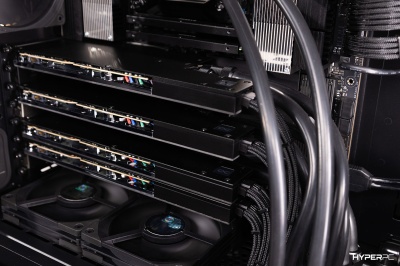
A flagship platform for local training, fine-tuning, and inference of large language models (LLMs). A dual-processor server architecture with PCIe 5.0 minimizes bottlenecks and latency when working with PyTorch, DeepSpeed, vLLM, and TensorRT.
Make to order
Ways to receive
Choosing a new computer. I still have questions. I need the advice of an expert.
Ways to receive an order
-
Loading shipping optionsCouldn't find any shipping options. Choose another location or contact us and we'll be sure to work something out.- United Arab Emirates
- Bahrain
- Kuwait
- Oman
- Qatar
- Saudi Arabia
-
Pickup from store
-
 DubaiBelresheed Building, Office 8, Nad Al Hamar, Dubai, UAE, 10 AM - 7 PM, Monday to FridayPickup on 10 October
-
Equipment HYPERPC AMPERE 9 ULTRA
CPU
AMD Ryzen Threadripper PRO 9995WX [up to 5.4GHz, 96 cores]
AMD Ryzen Threadripper PRO 9995WX workstation processor with 96 cores, 192 threads, up to 5.4 GHz, DDR5-6400 ECC support, and 350 W TDP.
GPU
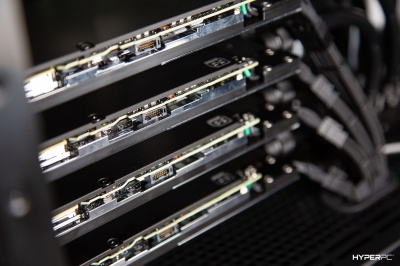
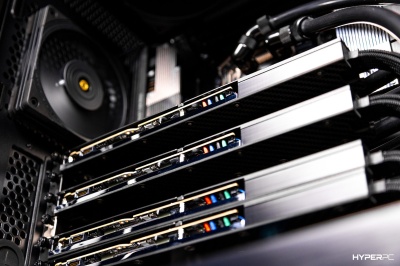
NVIDIA RTX PRO 6000 Blackwell Workstation Edition [96GB, 24064 CUDA]
NVIDIA RTX PRO™ 6000 Blackwell Workstation Edition is the most powerful desktop graphics processor ever created, redefining performance and capabilities for professionals. Based on the revolutionary NVIDIA Blackwell architecture and equipped with 96 GB of ultra-fast GDDR7 memory, the RTX PRO 6000 delivers unprecedented speed, precision, and efficiency, enabling you to achieve the impossible.

Motherboard
ASUS Pro WS WRX90E-SAGE SE [DDR5]
The ASUS Pro WS WRX90E-SAGE SE is designed to unlock the incredible power of the latest AMD® Ryzen® Threadripper™ Pro series processors and serves as a reliable foundation for professional creative workloads that benefit from multi-core processors, such as video editing and 3D rendering. Additionally, seven PCIe 4.0 slots with SafeSlot protection ensure exceptional performance with the latest powerful graphics cards.

Cooling
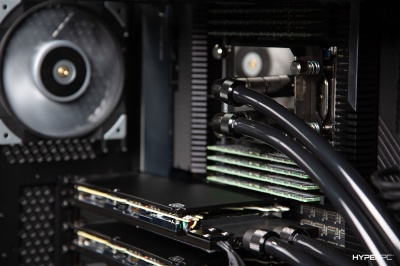
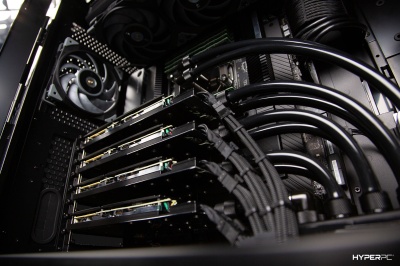
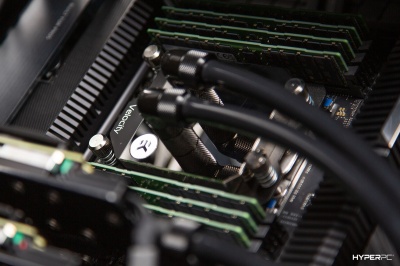
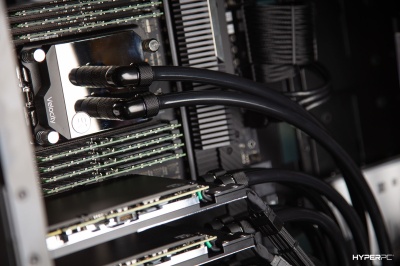
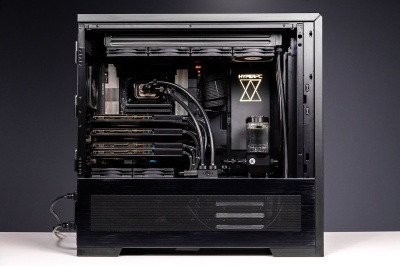
4xGPU and CPU water-cooling
A high-performance liquid cooling system for the processor and up to four graphics cards. It ensures stable GPU server operation even under extreme loads, lowering temperatures and extending component lifespan.
RAM
2048GB [DDR5, 4800MHz, 8x256GB RDIMM ECC]
This 2048 GB DDR5 ECC RDIMM memory kit includes 8 × 256 GB modules rated at 4800 MHz. It is configured for systems that require error-correcting memory for reliable operation under sustained workloads.

SSD
2TB Samsung 9100 PRO [14700MB/s, Gen5]
A flagship SSD built for those who demand absolute performance from their PC. With a PCI-E 5.0 x4 interface and NVMe support, this drive boosts your system to incredible speeds — up to 14,700 MB/s read and 13,400 MB/s write. These figures make it the perfect choice for gamers, professional video editors, 3D designers, and anyone working with large volumes of data.
HDD
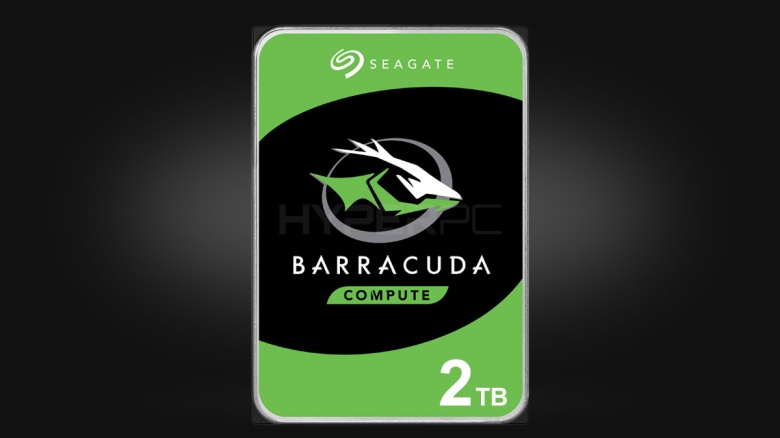
2TB Seagate BarraCuda [190MB/s, 7200RPM]
This Seagate BarraCuda hard drive provides 2 TB of storage in a 3.5-inch SATA 6 Gb/s format and operates at 7200 RPM. Its exact transfer rate remains SKU-dependent and must be confirmed before publication.
Power supply
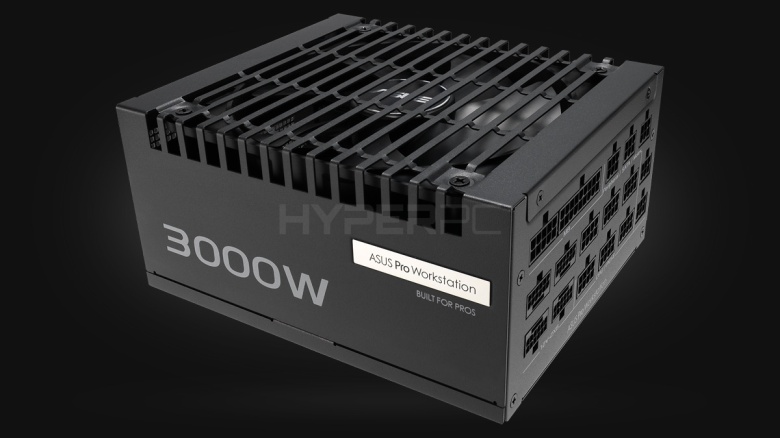
3000W ASUS Pro WS Platinum
The ASUS Pro WS 3000W Platinum power supply delivers exceptional voltage stability and advanced power delivery capabilities for professionals, supporting up to four graphics cards for demanding AI workloads.
Cases
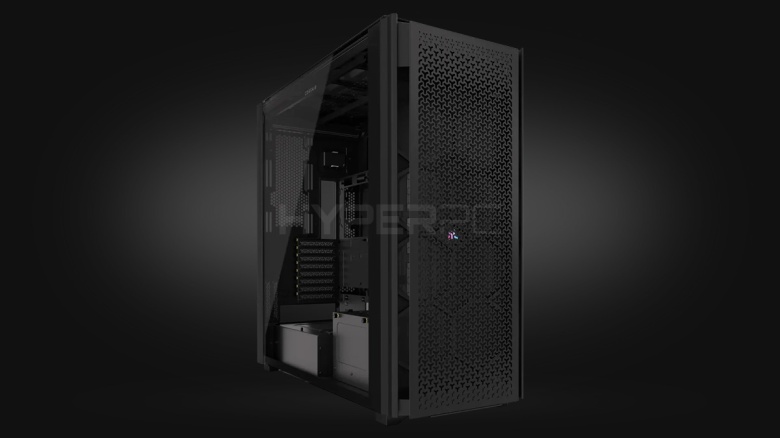
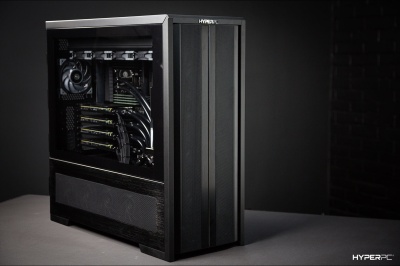
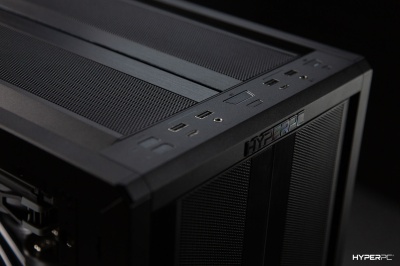
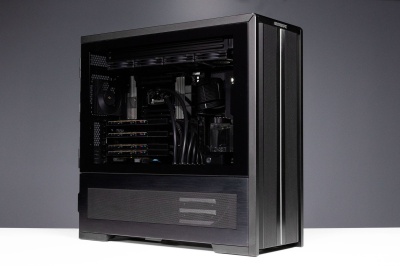
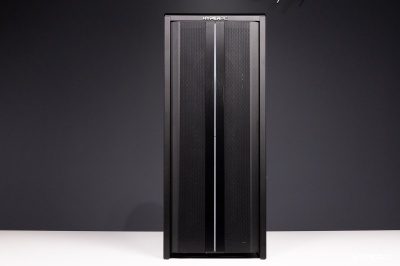
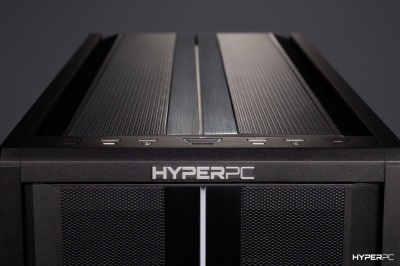
CORSAIR 9000D
The Corsair 9000D RGB AIRFLOW case builds upon CORSAIR’s award-winning case designs while introducing a host of innovations. Its massive interior supports a wide range of cooling configurations, accommodating up to eighteen 120mm, seven 140mm, or four 200mm fans. The steel front panel—designed for exceptional airflow—opens easily for cleaning and allows a massive intake of cool air to maximize the performance of your core components.

Fans
Thermaltake TOUGHFAN EX12 Pro High Static Pressure
TOUGHFAN - a fan with PWM control of blade rotation speed, which reaches a maximum of 2000 RPM. Provides unparalleled cooling efficiency, which is relevant for powerful workstations and gaming computers.

OS
Windows 11 Pro
Windows 11 is a calm and creative space where you can continue your passions and expand them with new features. From a redesigned Start menu to new ways to interact with your loved ones, news, games, and content, Windows 11 is a place where you can think, express yourself, and create in the most natural way possible. Maximize your performance.
Specifications HYPERPC AMPERE 9 ULTRA
| Hardware | |
|---|---|
| GPU |
|
| CPU |
|
| Motherboard |
|
| RAM |
|
| Cooling |
|
| SSD |
|
| HDD |
|
| Power supply |
|
| Cases |
|
| Fans |
|
| Software | |
| OS |
|
 Arabic
 English